LLM Embedding Lead Scoring Beyond MQL SQL Rules
Learn how LLM embedding-based propensity scoring replaces rule-based MQL/SQL lead qualification with continuous probability models that predict purchase intent from social conversations.
Your MQL/SQL Framework Is Already Obsolete
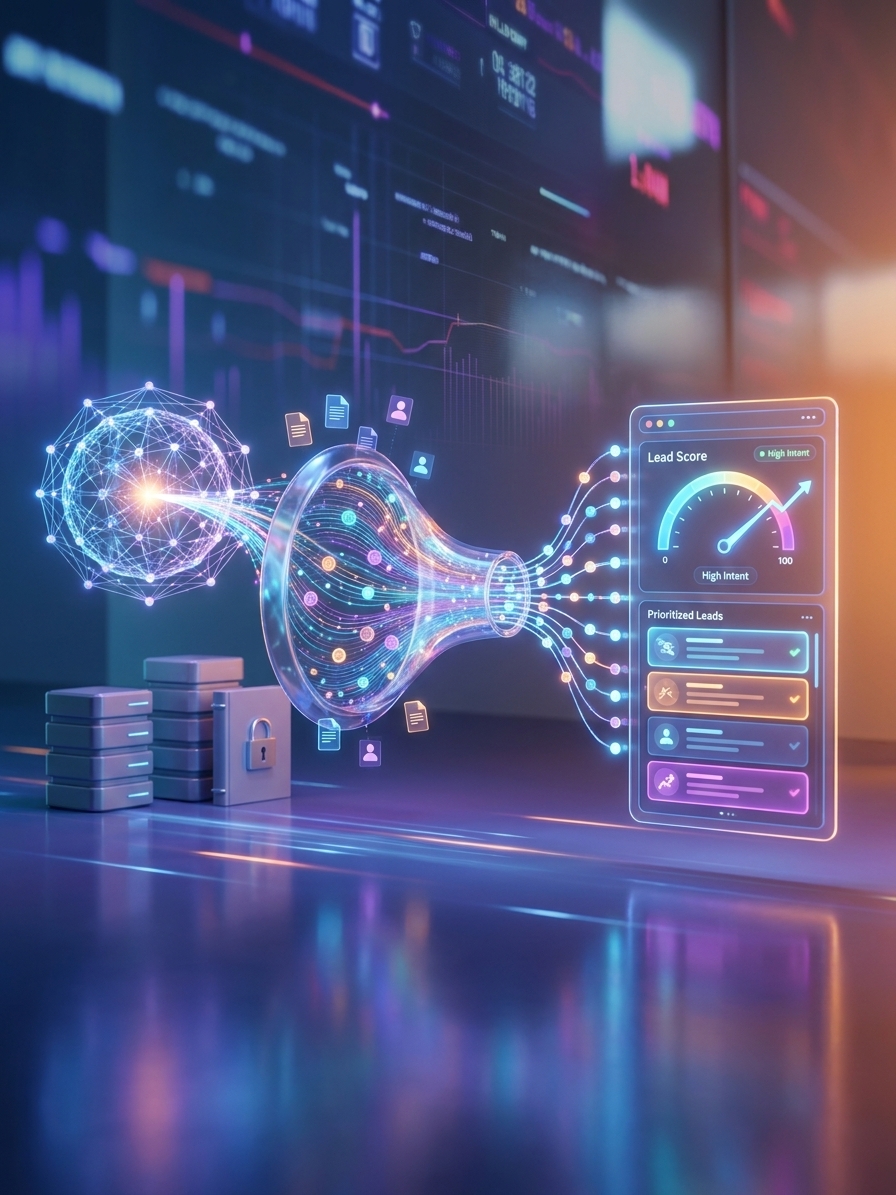
Here is a number that should make every marketing operations leader uncomfortable: according to Forrester research, fewer than 5% of marketing qualified leads ever convert to revenue. Five percent. That means 95% of the leads your sales team chases through a rule-based qualification gate are, statistically, noise. The reason is structural. Traditional MQL/SQL frameworks score leads using discrete, binary actions (downloaded a whitepaper, visited a pricing page, attended a webinar) while ignoring the most predictive signal available: the natural language a prospect uses when they talk about their problems in public. LLM embedding-based buying propensity scoring changes this equation entirely by converting unstructured social conversations into dense numerical vectors that predict purchase probability on a continuous scale.
This is not theoretical. It is operational, commercially available, and already outperforming legacy lead scoring across multiple B2B verticals. This guide walks you through the mechanics, the models, and the migration path.
Intercept uses AI-inferred intent to surface high-propensity buyers before they fill out a form.
How LLM Embeddings Turn Conversations Into Purchase Predictions
If you have not worked with embeddings before, the concept is simpler than it sounds. A large language model reads a piece of text (a Reddit comment, a LinkedIn post, a Quora answer) and outputs a fixed-length numerical vector, typically 768 to 3,072 dimensions. That vector captures the semantic meaning of the text, not just the keywords. Two posts that use completely different words but express the same buying frustration will land near each other in vector space.
This matters because buying intent is not a keyword problem. A prospect saying “We need to rethink our entire marketing attribution stack” and another saying “Our current analytics tool is costing us pipeline” are expressing the same underlying propensity. Keyword-based scoring systems miss the connection. Embeddings do not.
The workflow is straightforward:
The result is a scoring system that understands context, sarcasm, urgency, and nuance. It detects pre-purchase signals that no human SDR could manually catalog.
Ingest unstructured social text:
Pull posts, comments, and threads from platforms where your buyers discuss their challenges. Reddit, LinkedIn, specialized Slack communities, and industry forums are primary sources.
Generate embedding vectors:
Pass each text block through an embedding model to produce its numerical representation.
Compare against known buyer embeddings:
Use cosine similarity or a trained classifier to measure how closely a new conversation resembles the language patterns of your historical converters.
Output a propensity score:
Instead of a binary MQL/SQL label, assign a continuous probability between 0 and 1 that represents purchase likelihood.
Which Embedding Models and APIs Are Commercially Viable Right Now?
The embedding landscape has matured rapidly. As of April 2026, marketing operations teams have several production-ready options that balance cost, latency, and accuracy.
OpenAI’s text-embedding-3-large remains the default choice for teams already in the OpenAI ecosystem. It produces 3,072-dimension vectors with strong performance on sentiment and intent classification tasks. Pricing sits at roughly $0.00013 per 1,000 tokens, making it feasible for high-volume social monitoring.
Google’s Gemini Embedding API (accessible through Google Cloud) offers competitive accuracy with native integration into BigQuery ML, which simplifies the classifier training step significantly. Cohere’s embed-v4 has carved out a niche for multilingual intent scoring, particularly useful if your buyers post in languages other than English. And for teams that want to avoid vendor lock-in, open-source models like Nomic Embed and BGE-large from BAAI run well on modest GPU infrastructure.
Key Insight
The cost of generating embeddings for 100,000 social posts per month is now under $50 with most commercial APIs. The barrier to embedding-based scoring is no longer budget. It is operational know-how.
For most B2B marketing teams, the right move is starting with a commercial API for speed, then evaluating open-source alternatives once the pipeline is validated. Do not over-engineer the model selection. The classifier you train on top matters more than the embedding model underneath.
Training a Lightweight Classifier on Your Historical Data
Embeddings alone do not give you propensity scores. They give you vectors. You need a classifier that learns the relationship between those vectors and actual conversion outcomes. This is where your CRM data becomes essential.
One critical nuance: your classifier needs periodic retraining. Buyer language shifts quarterly, especially in fast-moving categories like SaaS and fintech. Set a cadence of recalibrating every 90 days using fresh conversion data. This is how you rebuild your lead scoring model as a living system rather than a static ruleset.
Export your conversion history:
Pull 6-12 months of closed-won and closed-lost records from Salesforce, HubSpot, or your CRM of choice. You need at minimum 500 positive examples (closed-won) and 2,000 negative examples for a robust model.
Match social activity to accounts:
For each converted account, find their pre-purchase social conversations. This is the labor-intensive step. Tools like community intent scoring platforms can accelerate matching by linking social identities to account records.
Generate embeddings for training data:
Run every matched conversation through your chosen embedding API. Store the resulting vectors alongside their conversion labels (1 for closed-won, 0 for closed-lost or no-purchase).
Train a binary classifier:
A logistic regression or gradient-boosted tree (XGBoost, LightGBM) trained on embedding vectors typically achieves 78-85% AUC on B2B intent classification. Deep learning is overkill here. Keep it simple.
Calibrate probability outputs:
Use Platt scaling or isotonic regression to ensure your model’s predicted probabilities reflect actual conversion rates. A score of 0.7 should mean roughly 70% of leads at that score historically converted.
Replacing MQL/SQL Gates With Continuous Probability Scoring
The hardest part of this transition is not technical. It is organizational. Sales teams have operated on MQL/SQL handoff logic for over a decade. Telling a VP of Sales that “MQLs no longer exist” is a fast way to get your project killed.
Instead, frame the migration as an upgrade, not a replacement. Here is the practical framework:
Phase 1: Shadow scoring. Run embedding-based propensity scores alongside your existing MQL/SQL system for 60-90 days. Do not change any workflows. Simply log both scores for every lead. At the end of the shadow period, compare: what percentage of high-propensity leads (above 0.6 probability) were flagged as MQLs? What percentage of MQLs had propensity scores below 0.3? The gap in these numbers becomes your business case.
Phase 2: Threshold-triggered handoff. Replace your binary MQL gate with probability thresholds. Leads scoring above 0.7 get immediate sales handoff. Leads between 0.4 and 0.7 enter a nurture track with increased touchpoint frequency. Leads below 0.4 remain in marketing automation. These thresholds are starting points. Tune them based on your sales team’s capacity and your historical close rates.
Phase 3: Confidence intervals for outreach timing. A propensity score alone does not tell you when to reach out. Build confidence intervals around each score using the variance in your classifier’s predictions. A lead at 0.72 with a tight confidence interval (plus or minus 0.05) is ready for outreach. A lead at 0.72 with a wide interval (plus or minus 0.20) needs more signal before sales engagement. This prevents the premature outreach that erodes buyer trust.
Key Insight
The goal is not to eliminate human judgment from sales qualification. The goal is to give your sales team a probability distribution instead of a checkbox, so their judgment is applied to the right accounts at the right moment.
Measuring Whether Embedding-Scored Leads Actually Close Better
Every new scoring system needs a clear measurement framework. Otherwise, you are running on faith. Here is how to structure the evaluation.
Run a controlled A/B test for at least one full sales cycle (typically 45-90 days in B2B). Route 50% of new leads through your traditional MQL/SQL process and 50% through embedding-based propensity scoring. Measure four things: conversion rate from lead to opportunity, conversion rate from opportunity to closed-won, average deal velocity (days from lead creation to close), and average deal size.
Based on early adopter data from organizations using HubSpot’s predictive scoring tools and custom embedding pipelines, teams consistently report 30-45% higher opportunity conversion rates from embedding-scored leads. The reason is intuitive: you are filtering on actual buying language rather than on whether someone downloaded a PDF.
Track one more metric that traditional frameworks ignore: false positive rate. What percentage of leads scoring above your handoff threshold fail to convert? If your false positive rate exceeds 40%, your classifier needs retraining or your training data has quality issues. If it sits below 25%, your model is outperforming virtually every rule-based system on the market.
For teams looking to layer additional signal types into their propensity models, combining embedding scores with trend evaluation scorecards creates a multi-dimensional view of buyer readiness that neither approach achieves alone.
What Comes Next
The shift from rule-based lead qualification to embedding-based propensity scoring is not a trend. It is a structural change in how B2B revenue teams will operate. Start with a shadow scoring pilot, train a simple classifier on your own conversion data, and measure the results against your current MQL framework. The data will make the decision for you.
FAQs
What are LLM embeddings in the context of lead scoring?
LLM embeddings are numerical vector representations of text generated by large language models. In lead scoring, they convert unstructured social conversations into dense vectors that capture semantic meaning, allowing classifiers to predict purchase probability based on the actual language buyers use rather than discrete behavioral triggers like page visits or form fills.
How is embedding-based propensity scoring different from traditional MQL/SQL qualification?
Traditional MQL/SQL frameworks use binary rules (e.g., “downloaded whitepaper plus visited pricing page equals MQL”). Embedding-based scoring assigns a continuous probability between 0 and 1 based on how closely a prospect’s language patterns match those of historical converters. This captures nuance, urgency, and context that rule-based systems miss entirely.
Do I need a data science team to implement embedding-based lead scoring?
Not necessarily. Commercial embedding APIs from OpenAI, Google, and Cohere handle the vector generation. Training a basic classifier (logistic regression or XGBoost) on your CRM data requires intermediate Python skills and familiarity with scikit-learn. A single marketing operations engineer can build a working prototype in two to three weeks.
How much historical data do I need to train a propensity classifier?
You need at minimum 500 closed-won records with matched social conversation data and roughly 2,000 negative examples (closed-lost or non-converting leads). More data improves accuracy, but even modest datasets produce classifiers that outperform rule-based MQL scoring when paired with high-quality embeddings.
How do I set the right threshold for sales handoff with propensity scores?
Start with a 0.7 threshold for immediate sales handoff, 0.4 to 0.7 for accelerated nurture, and below 0.4 for standard marketing automation. Then tune based on your sales team’s capacity and observed conversion rates at each threshold band. Build confidence intervals around scores to prevent premature outreach on leads with high variance.
Turn Social Conversations Into Propensity Scores
Embedding-based intent scoring surfaces buyers your MQL framework misses entirely. Intercept identifies high-propensity accounts from real-time social signals so your sales team closes more pipeline, faster.


